
Text Generation
Transformers
PyTorch
English
llama
medicine
doctor
custom_code
text-generation-inference
This model is the DeciLM-6b-Instruct model, trained specifically for medicine
Galen uses the
### User: {prompt}
### Response:
or
{prompt}
Prompt templates
Galen Training Recipe:
- target_modules = ["q_proj", "v_proj", "gate_proj", "down_proj", "up_proj", "k_proj", "o_proj"]
- Learning Rate: 4e-4
- LR Scheduler: constant
- 250 Steps
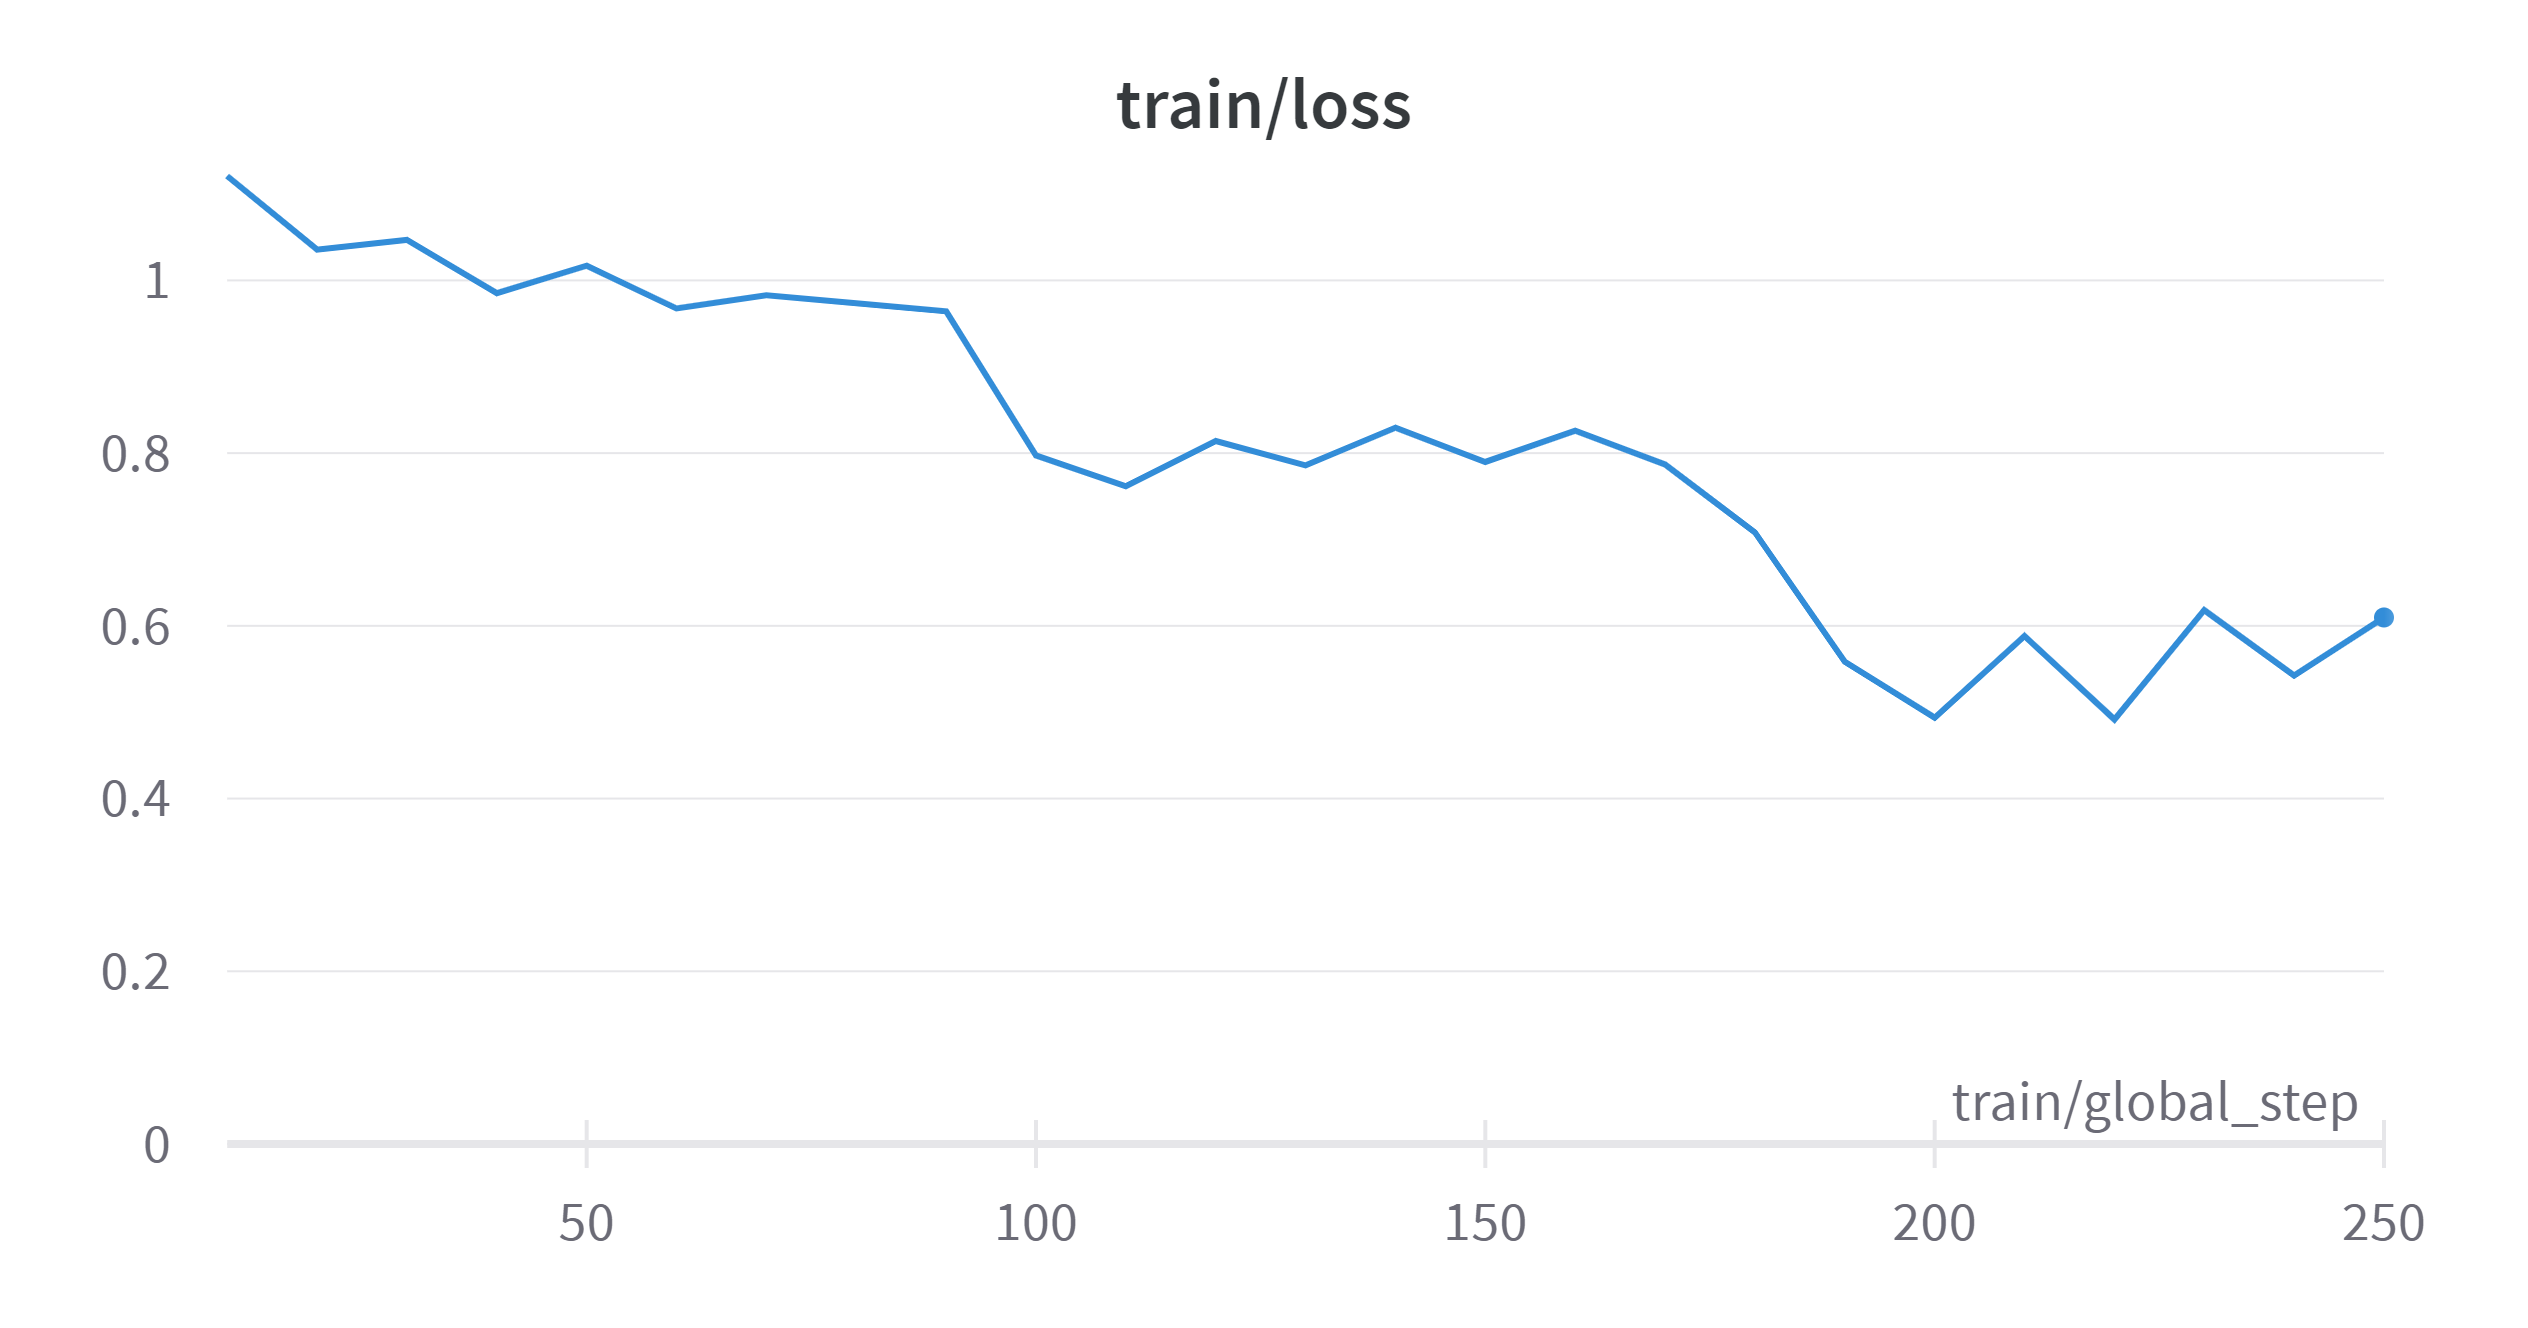
T3: 1 Hour
- Downloads last month
- 148
Install from pip and serve model
# Install vLLM from pip: pip install vllm# Start the vLLM server: vllm serve "NewstaR/StableGalen-6b"# Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "NewstaR/StableGalen-6b", "prompt": "Once upon a time,", "max_tokens": 512, "temperature": 0.5 }'